 coco
46 KiB
title, source, author, published, created, description, tags
| title | source | author | published | created | description | tags | ||
|---|---|---|---|---|---|---|---|---|
| Harness Engineering for Self-Improvement | https://lilianweng.github.io/posts/2026-07-04-harness/ |
|
2026-07-04 | 2026-07-08 | The concept of recursive self-improvement (RSI) dates back to I. J. Good (1965), where he defined an “ultraintelligent machine” as a system that can surpass humans in all intellectual activities and design better machines to improve itself. Yudkowsky (2008) used the phrase “recursive self-improvement” for a specific feedback loop: an AI uses its current intelligence to improve the cognitive machinery that produces its intelligence.This feedback loop in modern AI may indicate the model rewriting its own weights directly, or more broadly the model improves the training pipeline and the deployment system, which in turn enables a better successor model with improved performance across economically valuable tasks. The speed of research development in AI has been shown to drastically accelerated in frontier labs (Anthropic; OpenAI). |
|
递归式自我改进(RSI) 的概念 可以追溯到 I.J. Good(1965) ,他将“超智能机器”定义为一种能够在所有智力活动中超越人类,并能设计出更优秀的机器来改进自身的系统。Yudkowsky (2008) 则用“递归式自我改进”来描述一种特定的反馈循环:人工智能利用其当前的智能来改进产生自身智能的认知机制。
现代人工智能中的这种反馈循环可能意味着模型直接重写自身的权重,或者更广泛地说,模型改进了 训练流程 和 部署系统,进而催生出性能更优的后续模型,从而在具有经济价值的任务中脱颖而出。人工智能研究的进展速度在前沿实验室( 例如 Anthropic 和 OpenAI ) 中已显著加快。
我特意提到 “部署系统”, 是因为原始模型与真实世界环境之间的这层机制似乎与模型的原始智能(即预训练后的评估)同样重要。正如 Claude Code 和 Codex 等成功的编码代理产品所展示的那样,部署系统是人工智能部署的重要组成部分。 部署 系统围绕基础模型构建,负责协调执行,决定模型的思考和规划方式、工具调用和行动方式、感知和管理环境、存储工件以及评估结果。
本文将重点探讨线束工程及其对 RSI 的贡献。许多近期关于自动研究、自改进智能体和进化程序搜索的研究都可以围绕这一问题展开。其他关于模型自博弈、合成数据、测试时训练以及更广泛的持续学习主题的研究也符合 RSI 的愿景(例如 Yuan 等人,2024 ; Chen 等人,2024 ; Zhao 等人,2025 ; Choi 等人,2026 ),但它们并非本文的重点。
线束设计模式
与 早期的代理框架 (即“代理 = 逻辑逻辑模型 + 内存 + 工具 + 规划 + 行动”)相比,如今的代理工程还包含了 工作流设计(例如循环工程)、评估、权限控制和持久状态管理 。它不再仅仅是提示模板,而是更接近运行时和软件系统设计:模型如何观察、行动、记忆、自我检查和改进。
设计应力求简洁通用,以便于推广应用,并可能参考现有的软件工程实践,从而借鉴已有的知识。操作系统和框架之间存在着很强的相似性。与操作系统类似,框架也应封装复杂的逻辑,同时保持接口的简洁性。与此同时,配置、工具接口和其他协议可能会逐步在行业内实现标准化。
模式 1:工作流自动化
定义一个模型可以运行、测试和迭代的工作流程是自动化设计的关键。Karpathy 的 autoresearch 代码库( https://github.com/karpathy/autoresearch )就是一个构建此类工作流程的清晰示例。常见的工作流程遵循一个以目标为导向的循环:计划、执行、观察/测试、改进,然后再次执行, 直到 目标达成。该过程可能会主动向用户发出请求,以明确任务规范或执行偏好。
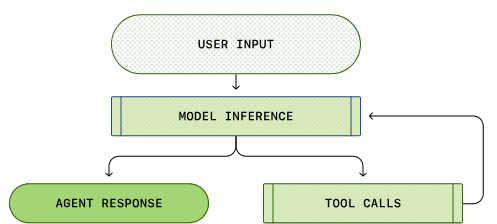
简化的 Codex 代理循环:代理调用工具,工具的响应会影响模型的下一代。 (图片来源: OpenAI Codex 代理帖子 )
工作流程图还强调模型分析自身的轨迹和失败案例,然后通过“代理运行时”迭代其进展,而不是使用静态提示模板。
模式 2:文件系统作为持久内存
长周期智能体系统中一个反复出现的模式是对丰富的状态和工件进行简单的控制。一个框架不应该承载整个工作流程和所有上下文日志;相反,它应该将持久状态保存在文件中。在长周期智能体部署过程中,诸如实验日志、代码差异、论文摘要、错误跟踪和以往部署轨迹等工件通常会远远超出模型训练的上下文窗口。
学习如何读取、写入和编辑文件系统(通常通过 bash 命令)是 LLM 的基础技能,因此,以文件这种简单形式管理持久内存自然会受益于核心模型能力的提升。
模式 3:子代理和后端作业
一个代理框架可以生成多个子代理并行执行并监控后端作业。当主代理需要搜索多个假设、并发运行实验或在不污染主上下文的情况下委派独立的子任务时,这非常有用。父代理则需要一个小型进程管理器:启动作业、检查日志、取消失败的运行并将结果合并回主代理线程。
关键的设计选择在于明确并行性并使其可检查。如果子代理的输出仅存在于瞬态的聊天上下文中,它们很快就会过时并被隐藏。如果将它们存储为文件、日志和状态记录,模型就可以在中断后恢复,并根据自身的执行历史进行推理。
案例研究:编码代理工具
主流编码代理的核心接口在 Claude Code、Codex、OpenCode 和 Cursor 等代理中已经趋于稳定。它们通常使用类似这样的循环:
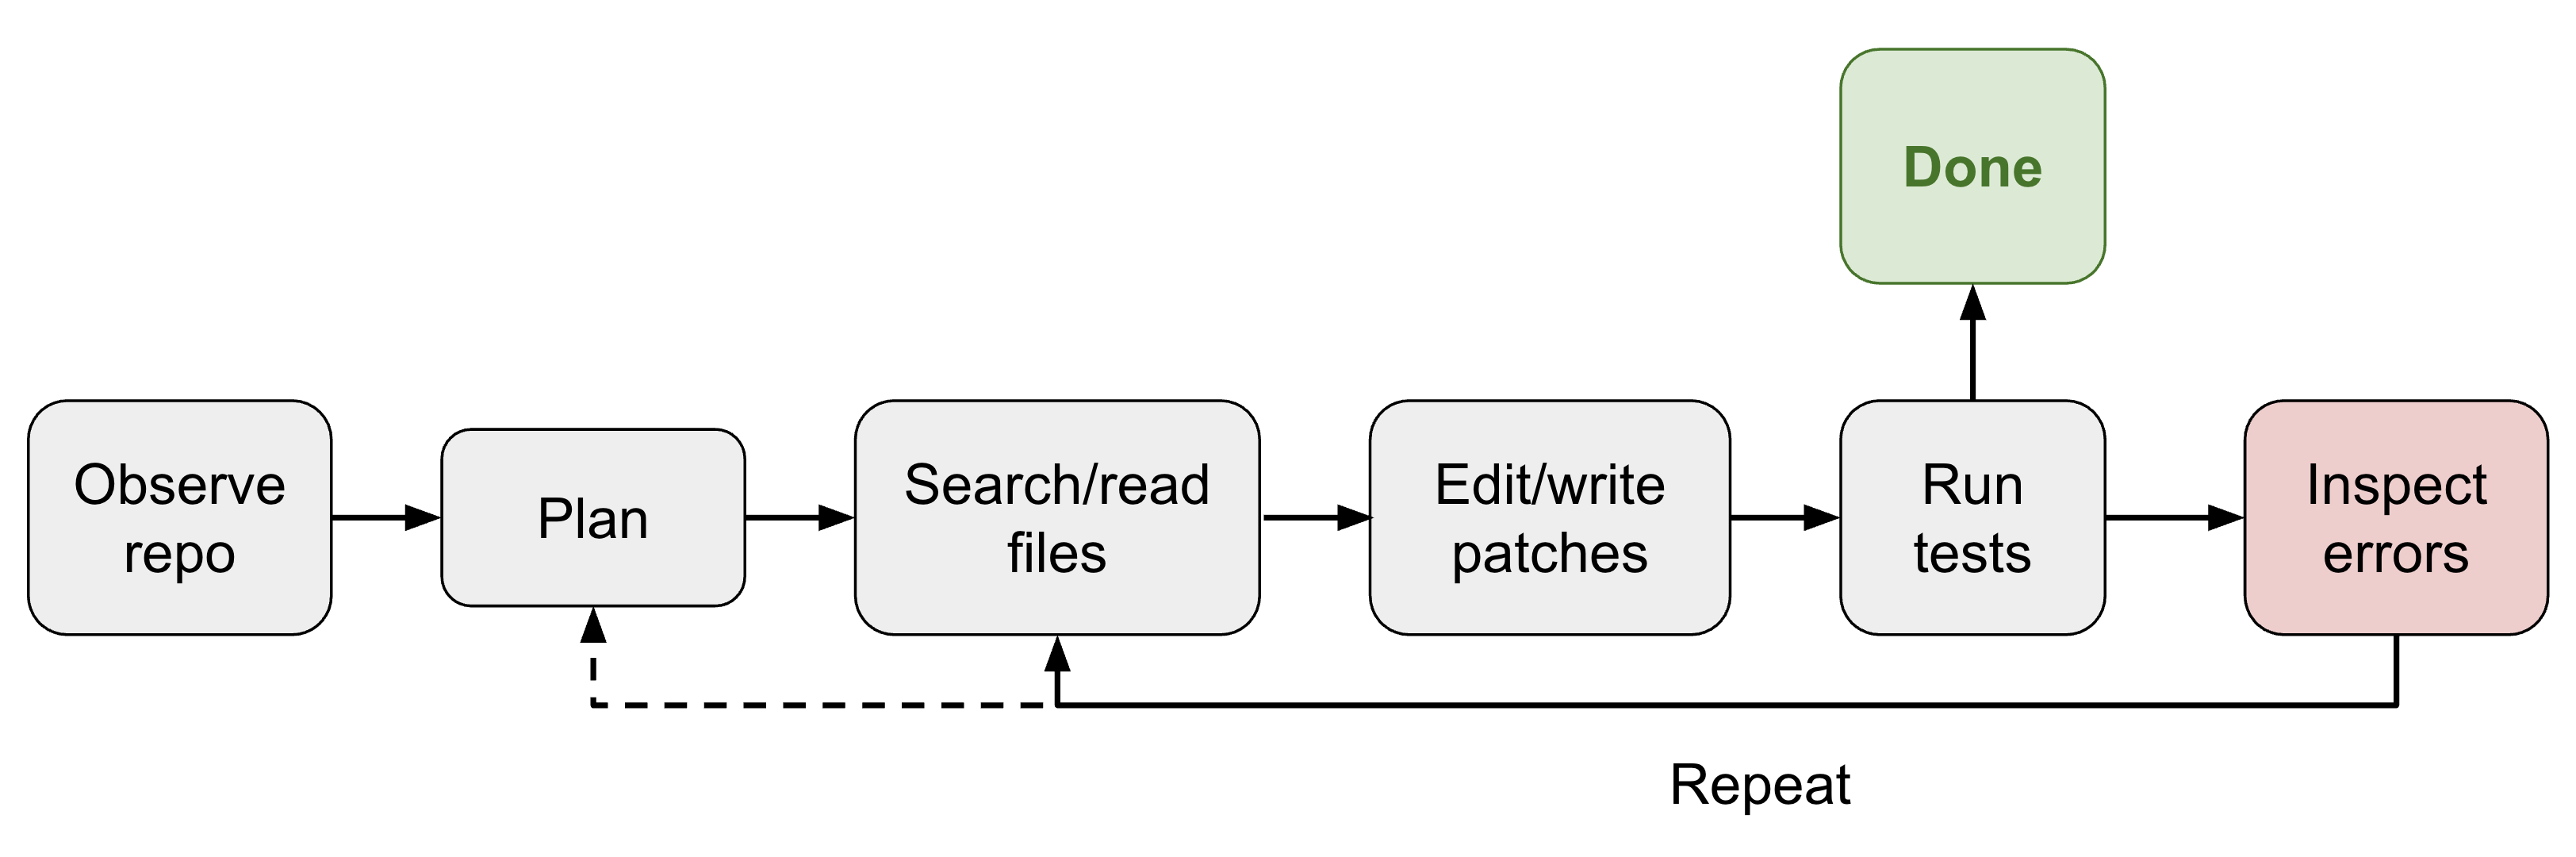
通过访问一系列工具,编码代理能够开发和调试给定存储库中的问题,类似于人类开发人员使用集成开发环境 (IDE) 的方式。
(此列表并不完整,仅作演示之用。如有兴趣,请阅读 原文 。)
| 团体 | 工具定义 |
|---|---|
| 文件系统 | - 文件发现: glob ,, grep - ls 文件读取: read , read_many - 文件修改:( write 新建一个文件); edit (字符串精确匹配替换);; multi_edit ( apply_patch 应用结构化补丁/差异) |
| Shell 执行 | 运行命令: bash , PowerShell |
| IO | lsp git 工具 如 git_status , git_diff git_commit |
| 外部环境 | MCP 工具、技能 |
| 网络搜索 | web_search 浏览 web_fetch 器工具 |
| 文物 | 读取文档、图像;生成 HTML、图像 |
| 后端流程 | 例如: CronCreate , CronDelete , CronList |
| 代理人委派 | 例如 : spawn_agent ,,,,,, 等等 。 resume_agent wait_agent list_agents close_agent interrupt_agent |
管理层与核心智能?
很难预测RSI的未来发展在多大程度上依赖于线束工程,但RSI的近期发展路径不太可能是从直接重写模型权重开始。我对近期切实可行的发展路径的预测是:
- 线束工程将朝着元方法论的方向发展(即改进获取更佳答案的机制,而不仅仅是改进答案本身)。线束系统本身将成为优化目标,减少启发式规则,采用更通用的机制。
- 反过来,成熟的框架能够实现模型自我改进循环的自动研究,而更智能的模型可以防止框架过度设计,并保持系统的可持续性。
最终,许多模型改进可能会 被内化 到核心模型行为中,但与外部上下文和工具的接口仍应保留。我们在 提示工程 中已经看到了这种模式的温和版本:随着指令调整和模型推理能力的提升,手动提示技巧的重要性有所降低,但 指定目标、约束、上下文和评估的需求并未消失 。
牵引优化
在模型优化系统中,待优化对象的迭代过程大致如下:指令 提示 → 结构化上下文 → 工作流 → 模型优化代码 → 优化器代码。随着模型变得更加智能和强大,我们会转向更复杂的目标和更通用的方法。
上下文工程
随着智能体任务范围的显著扩大,简单地将所有工具响应和模型生成结果添加到上下文中,很快就会变得难以控制。上下文管理层旨在为长上下文模型 (LLM) 构建一个更结构化、更简洁的上下文,并管理持久状态。毫无疑问,长上下文研究将持续取得进展,但目前长上下文智能和上下文工程有时会相互交织。
智能情境工程 (ACE; Zhang 等人,2025 )将情境视为不断演进的剧本,而非日益冗长的提示。它包含三个组成部分,用于维护一个由要点组成的情境剧本,每个要点都包含一个标识符和一个描述。
- 生成器 :根据要点生成任务轨迹。
- 反思者 :从成功和失败的轨迹中提炼洞见。
- 策展人 :通过逐步添加条目来更新结构化上下文。
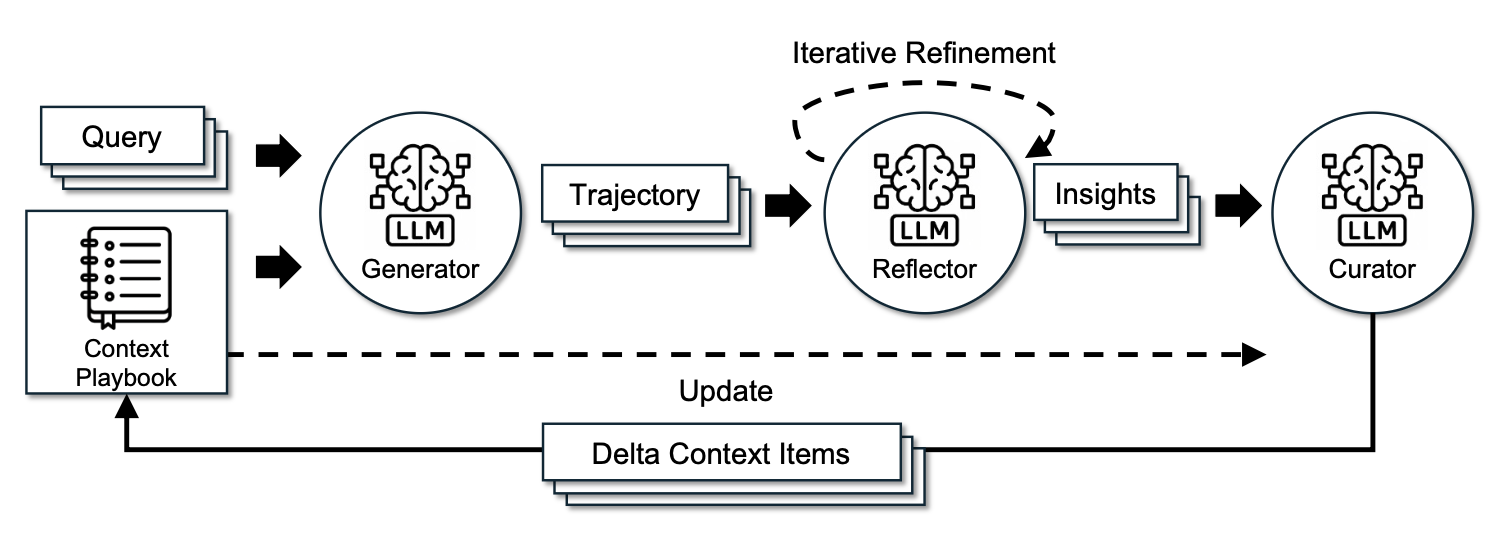
智能体情境工程(ACE)框架。(图片来源: Zhang et al. 2025 )
为了防止在迭代重写过程中出现上下文混乱和过于追求简洁的情况,ACE 的一个关键设计选择是:策展人不会重写完整的提示信息。相反,它会输出一系列结构化的、条目式的要点,格式为(标识符,描述)。这些要点会通过确定性逻辑合并到一个结构化的上下文日志中。上下文条目会定期进行完善和去重。
ACE 从部署过程中学习经验这一事实有助于我们实现内存的自我管理,但更新规则和整体工作流程仍然是手工设计的。为了构建更具自我改进性的循环, 元上下文工程 (MCE; Ye 等人,2026 )将机制(如何管理上下文)与工件内容(上下文中包含什么)分离,在元优化层面运行技能演化,在基础层面运行上下文优化。
MCE技能 \mathcal{} 定义上下文函数 _{} _{} _{} 并映射输入 $$ 上下文 _{} _{} , 在哪里:
_{} _{} _{}are static components (prompts, knowledge bases, code libraries).F_{s} = \left\{F_{1} , \ldots , F_{k}\right\}are dynamic operators (search, selection, filtering, formatting).
The bi-level optimization is to find the best context c_{s}^{*} given skill s on the training data, while the outer loop finds the optimal skill that provides the best performance on the validation set:
\text{Inner}:\text{ } c_{s}^{*} = arg \underset{c_{s}}{max} J_{\text{train}} \left(c_{s} ; s\right) \text{Outer}:\text{ } s^{*} = arg \underset{s \in \mathcal{S}}{max} J_{\text{val}} \left(c_{s}^{*}\right)
The skill database tracks the history of previous skills, context functions and eval metrics \mathcal{H}_{k - 1} = \left\{\right. \left(s_{i} , c_{i} , J_{i}^{\text{train}} , J_{i}^{\text{val}}\right) \left.\right\}_{i = 1}^{k - 1}. A meta-level agent performs agentic crossover over prior skills to create a new skill given a task \tau: s_{k} = \text{crossover} \left(\tau , \mathcal{H}_{k - 1}\right).
Then a base-level context engineer executes the skill s_{k} and learns the context function from rollout feedback \mathcal{R}_{k}, guided by the current skill: c_{k} = \text{engineer} \left(\tau , s_{k} ; c_{k - 1}^{*} , \mathcal{R}_{k}\right).
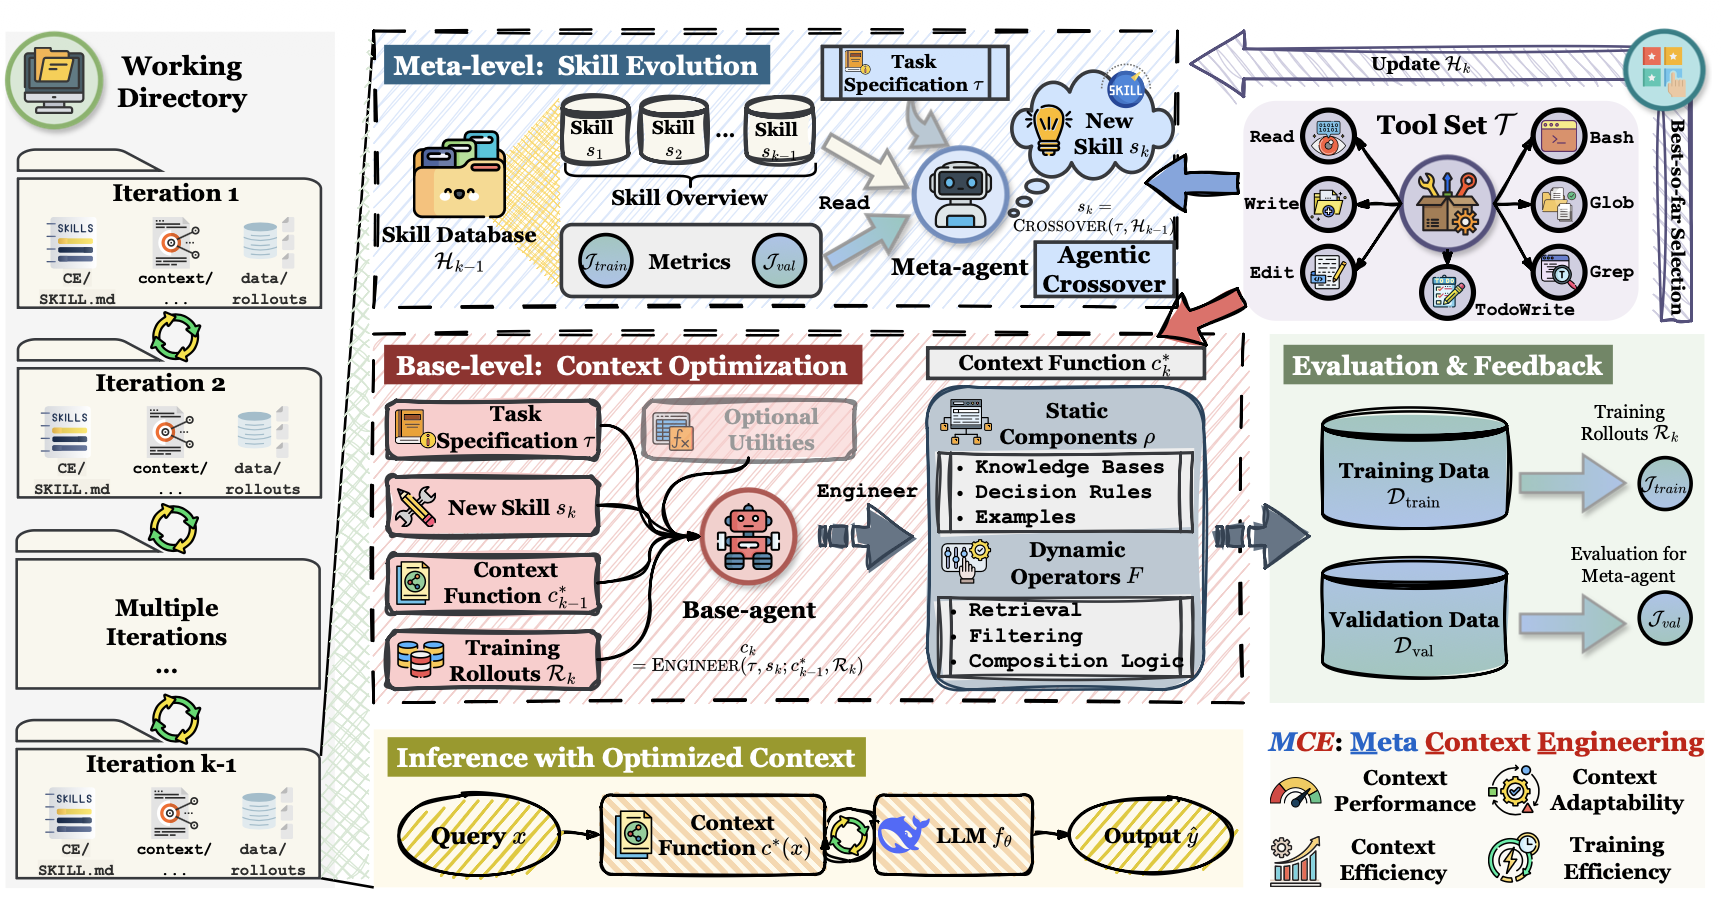
The framework of Meta Context Engineering (MCE): meta-level skill evolution searches over context-management mechanisms, while the base level optimizes the task context. (Image source: Ye et al. 2026 )
MCE does not enforce a heuristic rule for how to structure context as ACE does. It uses free-form skills to store the most important knowledge for a task, and evolves the skill and the skill-conditioned context iteratively together. Implementation-wise, a context function c is instantiated as a collection of files in a dedicated directory, including both static (skill.md) and dynamic (context and data rollouts) components. Both meta-level and base-level optimization are executed in agentic coding envs with a standard tool set,
\mathcal{T} = \left\{\mathtt{Read} , \mathtt{Write} , \mathtt{Edit} , \mathtt{Bash} , \mathtt{Glob} , \mathtt{Grep} , \mathtt{TodoWrite}\right\}
Meta-Harness (Lee et al. 2026) moves another level deeper: the optimized object is the code that determines and optimizes what information should be stored, retrieved, and presented to the model. “Meta-” in its name means it is a harness for optimizing harnesses.
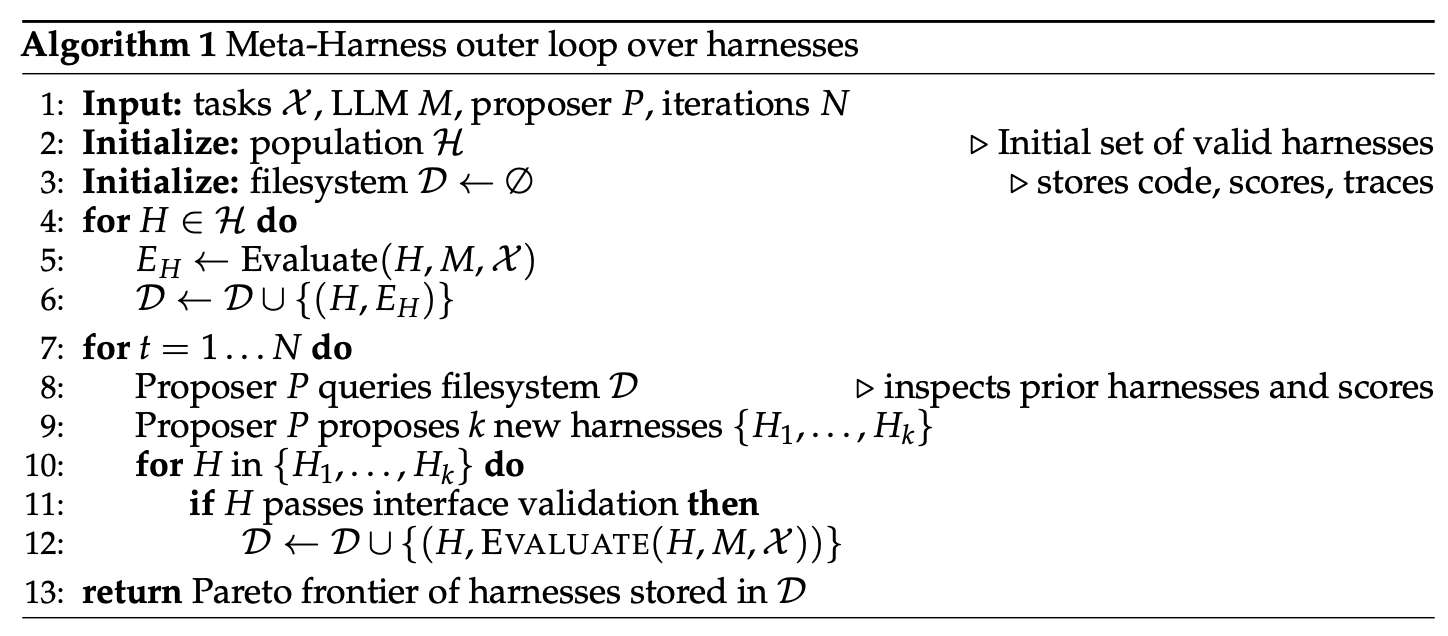
The Meta-Harness outer-loop optimization algorithm. (Image source: Lee et al. 2026 )
The proposer for creating a new harness is itself a coding agent and the final output is a collection of harness candidates on the Pareto frontier.
- The entire execution history is accessible via a file system, and thus the coding agent uses commands like
greporcatto read through it instead of shoveling everything into a single prompt context. - The proposed harness is a dictionary in the file system containing its own source code, scores, rollout trajectories, and state updates.
- The mete-harness loop iteratively creates new harnesses, and only qualified ones are kept.
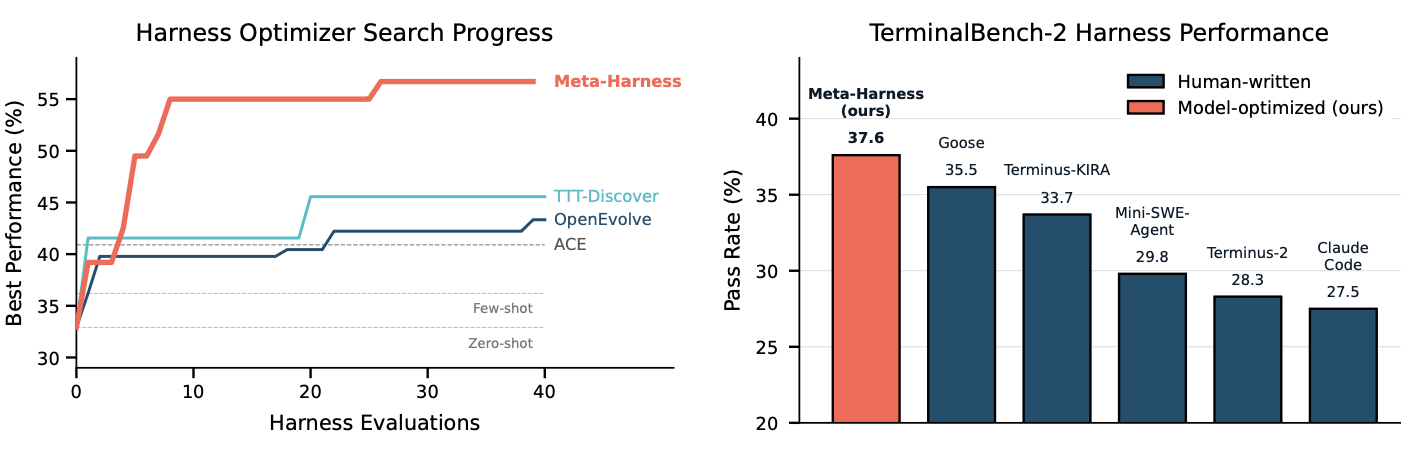
The performance of Meta-Harness on (Left) text classification with a small number of iterations and (Right) TerminalBench-2. Note that the search in the TerminalBench-2 experiment is initialized from Terminus-KIRA and Terminus-2, two very strong harnesses. (Image source: Lee et al. 2026 )
Still, the important lesson is clear: once harness design becomes an executable search space, a strong coding agent can exploit the same design space human engineers use.
Workflow Design
Workflow design in harness engineering can be handcrafted by domain experts. Taking auto-research as an example, various frameworks have been proposed and tested. The AI Scientist system (Lu et al. 2026) builds a pipeline to propose research ideas, write code, run experiments, analyze results, write a manuscript, and perform peer review. Meng et al. (2026) make verifiability the central design constraint in ScientistOne, where every claim (citation, numerical, methodological, conclusion) must trace to an evidence source and is audited by Chain-of-Evidence checks.
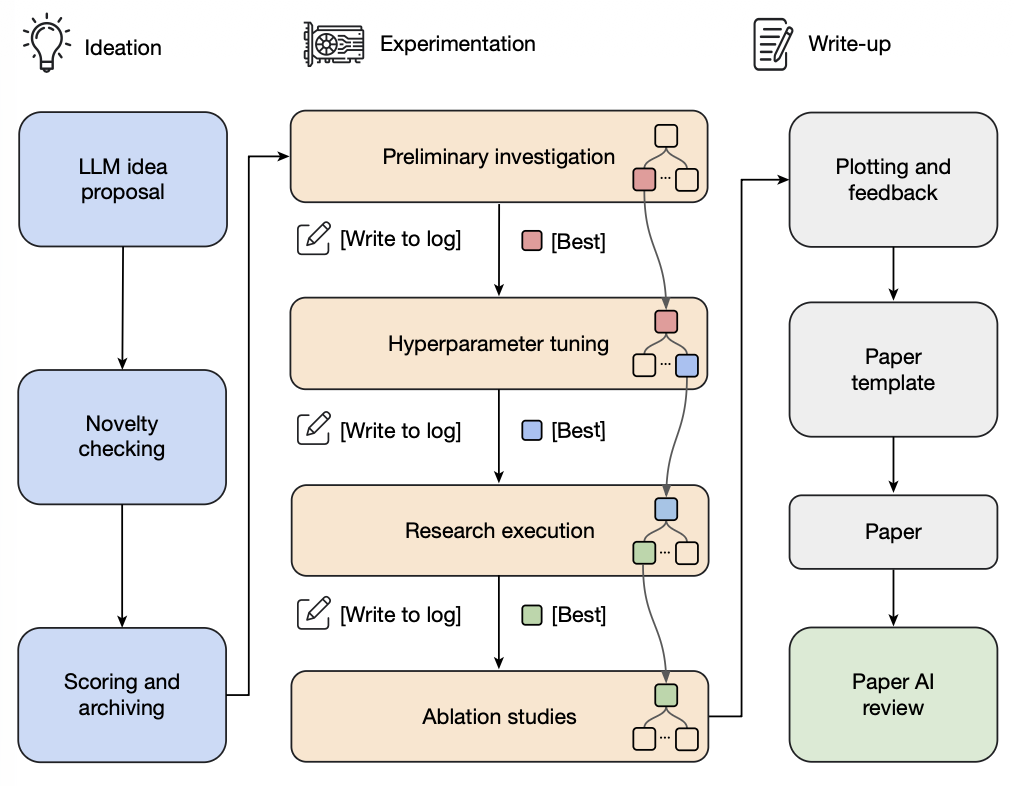
AI Scientist pipeline for idea generation, experimentation, paper writing, and review. (Image source: Lu et al. 2026 )
The Autodata agent (Kulikov et al. 2026) is designed to work as a data scientist for generating training and evaluation data. The main agent manages a challenger that proposes problems, a weak solver, a strong solver, and a verifier/judge, aiming to synthesize data at the “just right” level of difficulty, meaning that the strong solver succeeds but the weak solver fails.
In Autodata, the challenger prompt is updated iteratively according to feedback from the solvers and verifier. The limitation here is that synthesized tasks are used to fine-tune weak solvers but not strong solvers; if the loop cannot iteratively improve the strong model, it is more like indirect distillation over a generated prompt distribution, with less RSI flavor.
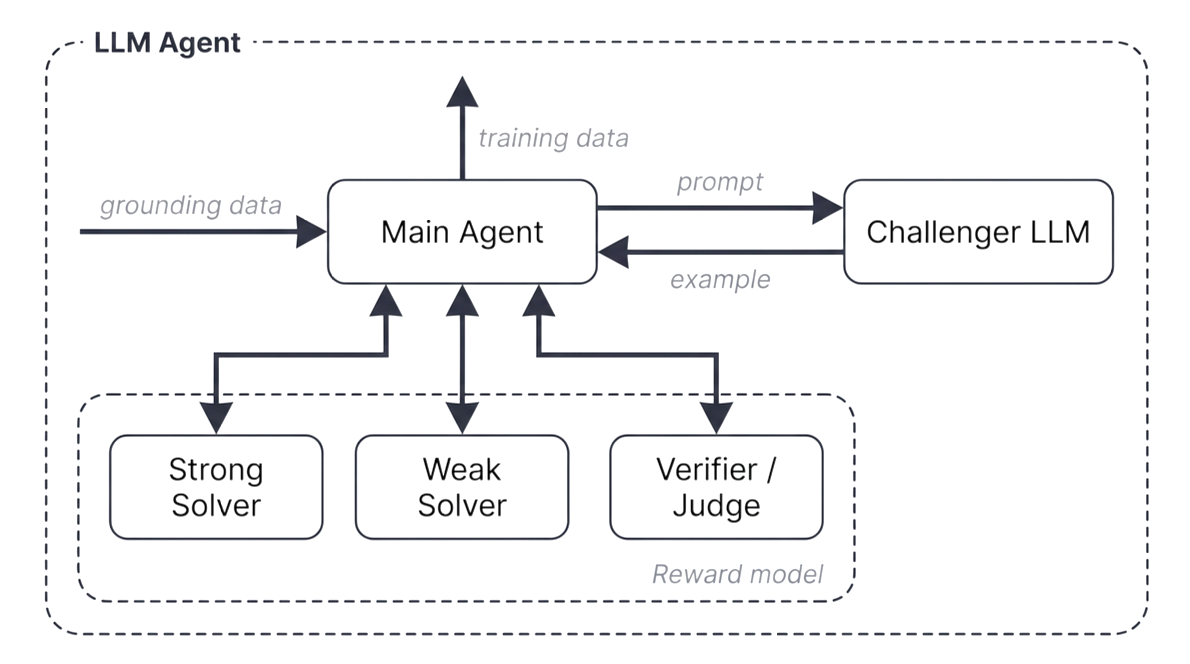
Autodata agentic workflow design for generating synthetic training and evaluation data around challenger, solver, and verifier roles. (Image source: Kulikov et al. 2026 )
The design space for workflow is enormous, and naturally we can think of workflow design as a search problem, and therefore we should be able to find good solutions by algorithms rather than only manually craft them. Following this direction, Automated Design of Agentic Systems (ADAS; Hu et al. 2025) formulates agent design itself as an optimization problem, “meta-agent search” where a meta-agent proposes new designs of agentic workflows.
- Initialize an archive of agentic workflows with simple agents such as CoT and self-refine.
- Ask a meta-agent to program new agents, all in code, inspired by existing solutions in the archive.
- The meta-agent first generates a high-level description of the new workflow, and then implements it in code.
- The draft program then goes through two self-refine steps (i.e. ask the model to provide feedback and then ask the same model to refine the previously generated outputs based on the feedback; Madaan et al. 2023) by the meta-agent to check its novelty.
- The meta-agent first generates a high-level description of the new workflow, and then implements it in code.
- Evaluate each new candidate and add successful ones back to the archive.
- Repeat steps 2-3 until the maximum iteration count is reached.
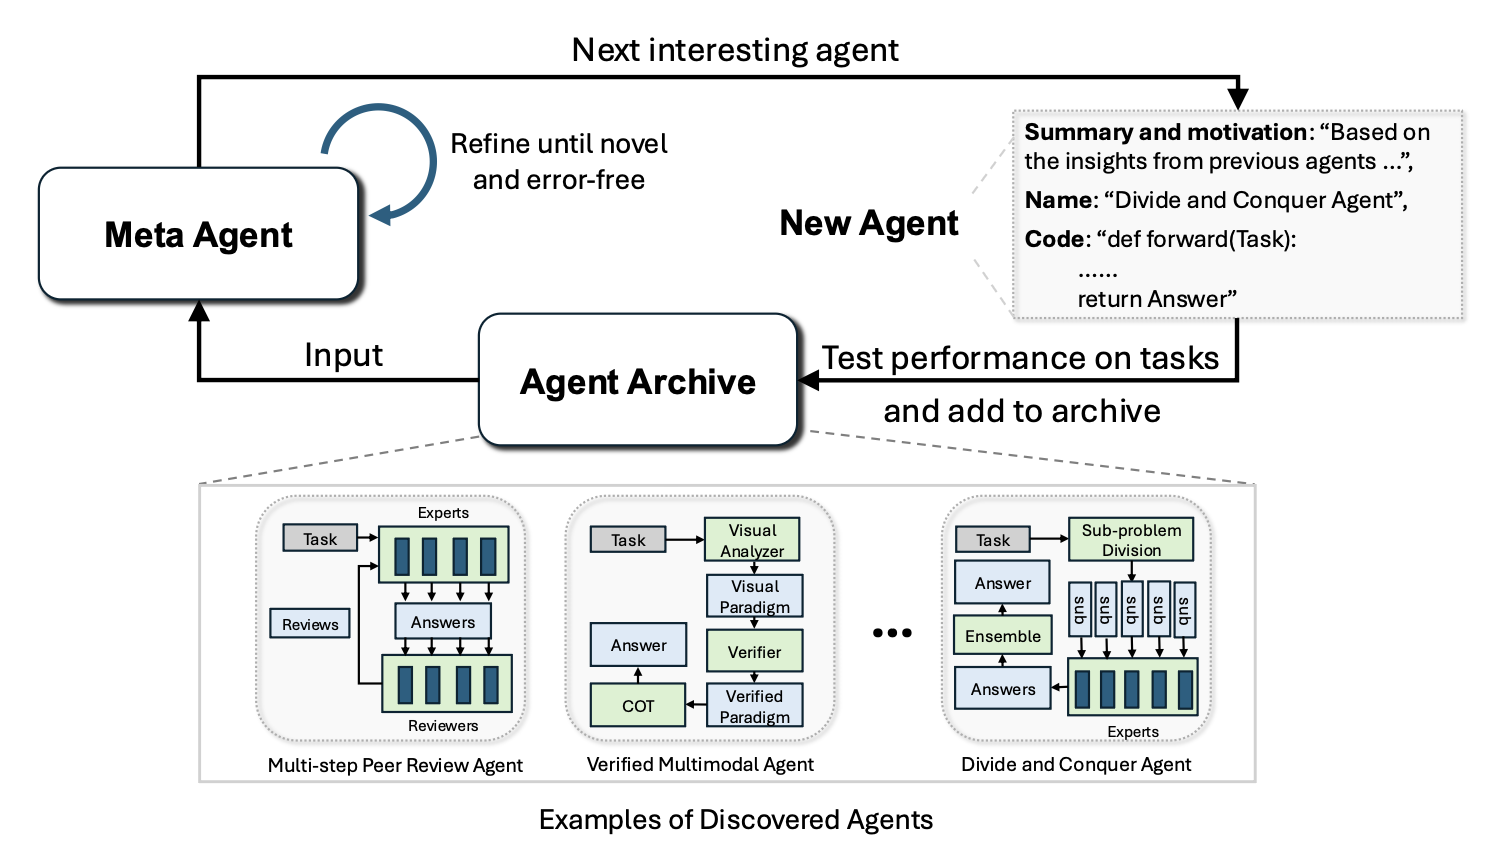
Illustration of Automated Design of Agentic Systems (ADAS). (Image source: Hu et al. 2025 )
AFlow (Zhang et al. 2025) represents an agentic workflow as a graph, where nodes represent LLM-invoking actions and edges implement logical operations in code. The workflow optimization relies on MCTS (Monte Carlo Tree Search):
- Initialize the starting workflow
W_{0}in the tree with a template. - Select a workflow node using a soft mixture of score and uniform exploration.
- Expand it by asking an LLM to produce a modified workflow conditioned on its evaluation performance.
- Execute and evaluate the new workflow.
- Add it back to the tree if the new workflow shows improvement within a budget of
Nrounds. - Repeat steps 2-5 and stop when the top-
kaverage score plateaus or hit the budget.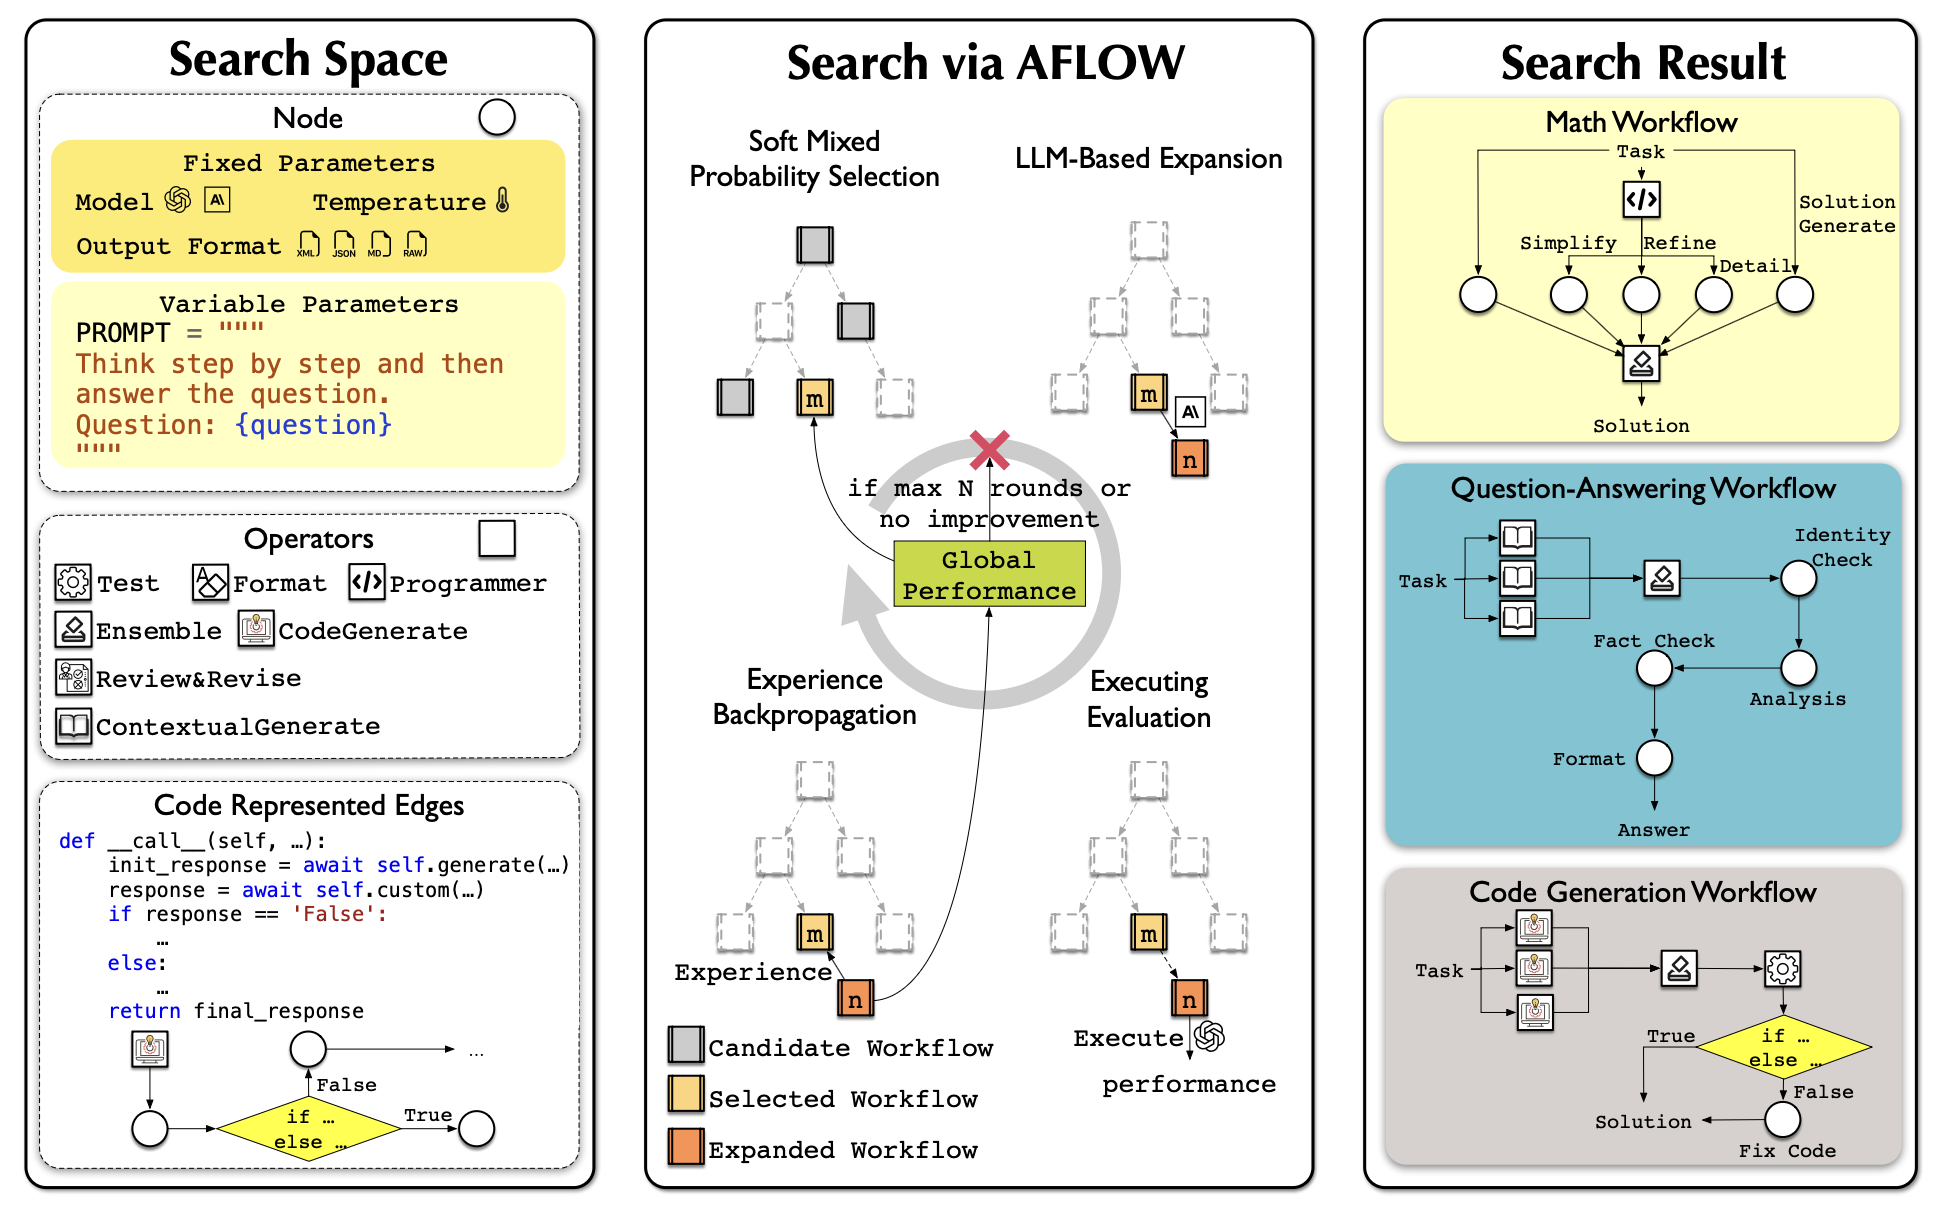
AFlow optimization process over a tree of workflow candidates. (Image source: Zhang et al. 2025 )
Experiments of AFlow in QA, code, and math tasks showed decent improvement of AFlow over manually designed workflows and ADAS.
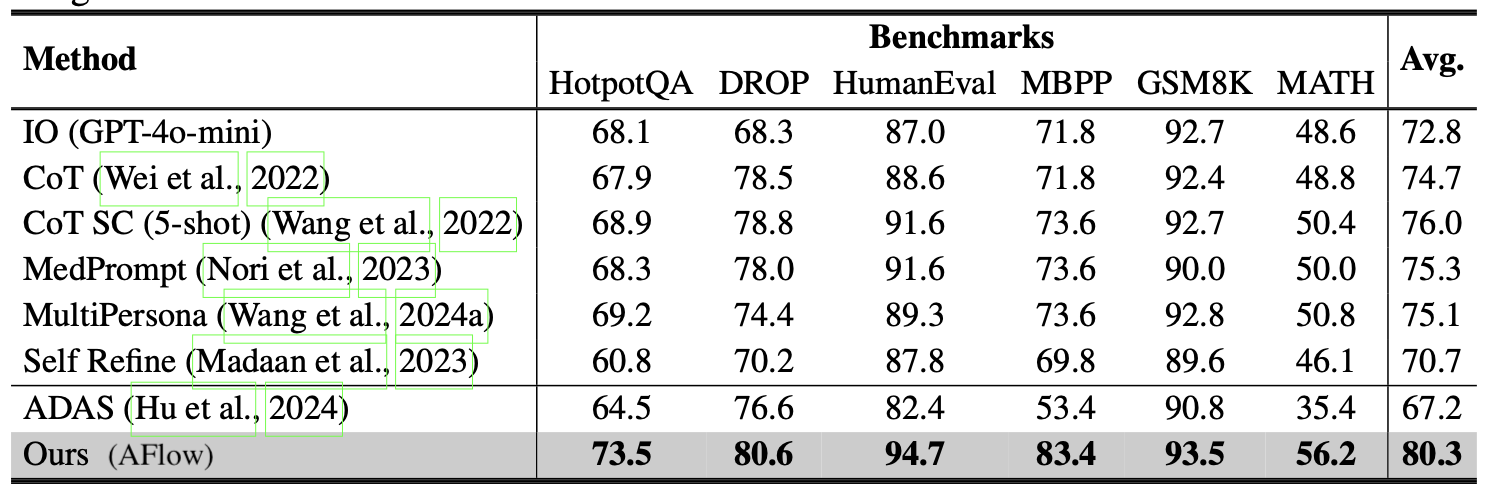
AFlow experiments in comparison to manual methods and ADAS. (Image source: Zhang et al. 2025 )
Self-Improving Harness
Either context engineering or workflow design is only one part of a harness. We need to search through the entire design space and optimize context-management logic, workflow, permissions, and many other harness components together. As we have seen in work like Meta-Harness, ADAS, and AFlow, ✨code✨ is a universal language for defining programs and systems. In simple words, a harness is code that programs how prompts, tool calls, subagents, control flow, memory, and workflow logic work together. If an LLM can optimize the code that executes agents, it can access a much larger design space than hand-written prompts.
Self-Taught Optimizer (STOP; Zelikman et al. 2023) is one of the early examples of recursive scaffolding improvement. A seed improver I_{0} at step t = 0 takes an initial solution s, a utility function u, and a black-box language model M, and returns an improved solution s^{'}, that is, s^{'} = I \left(u , s ; M\right). The goal of STOP is not directly to improve s but to improve the improver I itself.
First, let’s define the meta-utility as the average utility of a given improver function I over a collection of downstream tasks \mathcal{D}:
\hat{u} \left(I\right) \triangleq \frac{1}{\left|\mathcal{D}\right|} \mathbb{E}_{\left(u , s\right) \sim \mathcal{D}} \left[u \left(I \left(u , s ; M\right)\right)\right]
Because improving the improver function is an optimization problem itself, we can recursively get a new version of I_{t} based on I_{t - 1} ’s performance measured by meta-utility via a self-improvement update:
I_{t} = I_{t - 1} \left(\hat{u} , I_{t - 1} ; M\right)
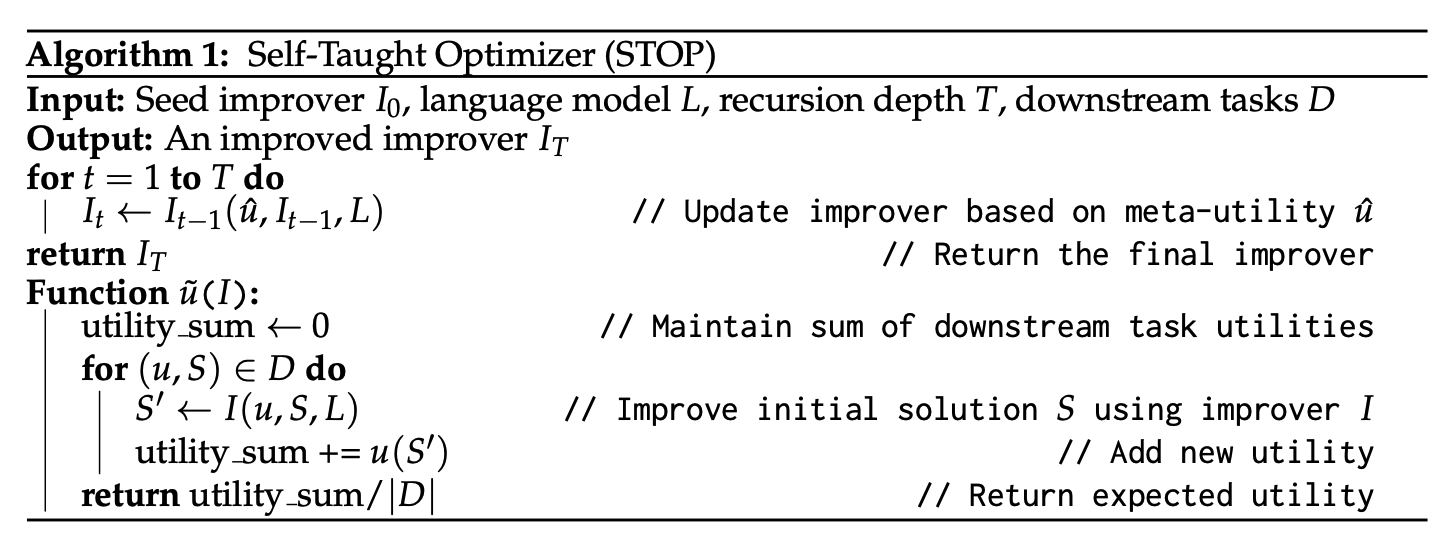
Algorithm of Self-Taught Optimizer (STOP). (Image source: Zelikman et al. 2023 )
In Zelikman et al. (2023)’s experiments, the improved improver discovered various strategies, such as genetic algorithms, decomposing and improving parts, multi-armed prompt bandits, simulated annealing, varying temperature, and beam/tree search. This is analogous to how a harness workflow can be represented as an object for optimization.
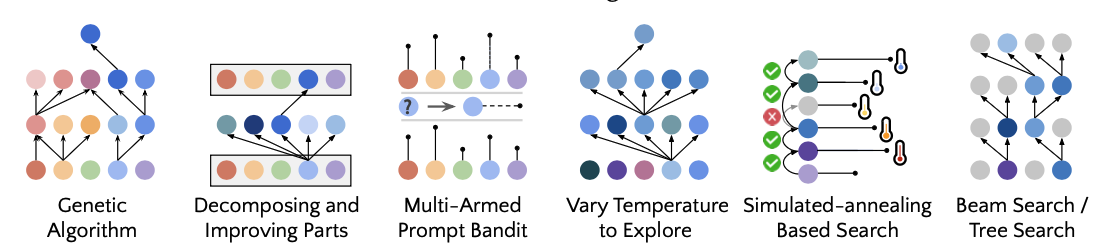
Examples of self-improvement strategies discovered by STOP. (Image source: Zelikman et al. 2023 )
A cautionary result in their findings is that STOP improved mean downstream performance across iterations with GPT-4 but degraded with weaker models like GPT-3.5 and Mixtral. Recursive structure alone is not enough. The base model must be capable enough to improve the mechanism. This implies that harness improvement enables better deployment of the model but intelligence is still the core.
A more recent work, Self-Harness (Zhang et al. 2026), relies on LLM agents to improve their own harness via a propose-evaluate-accept loop.
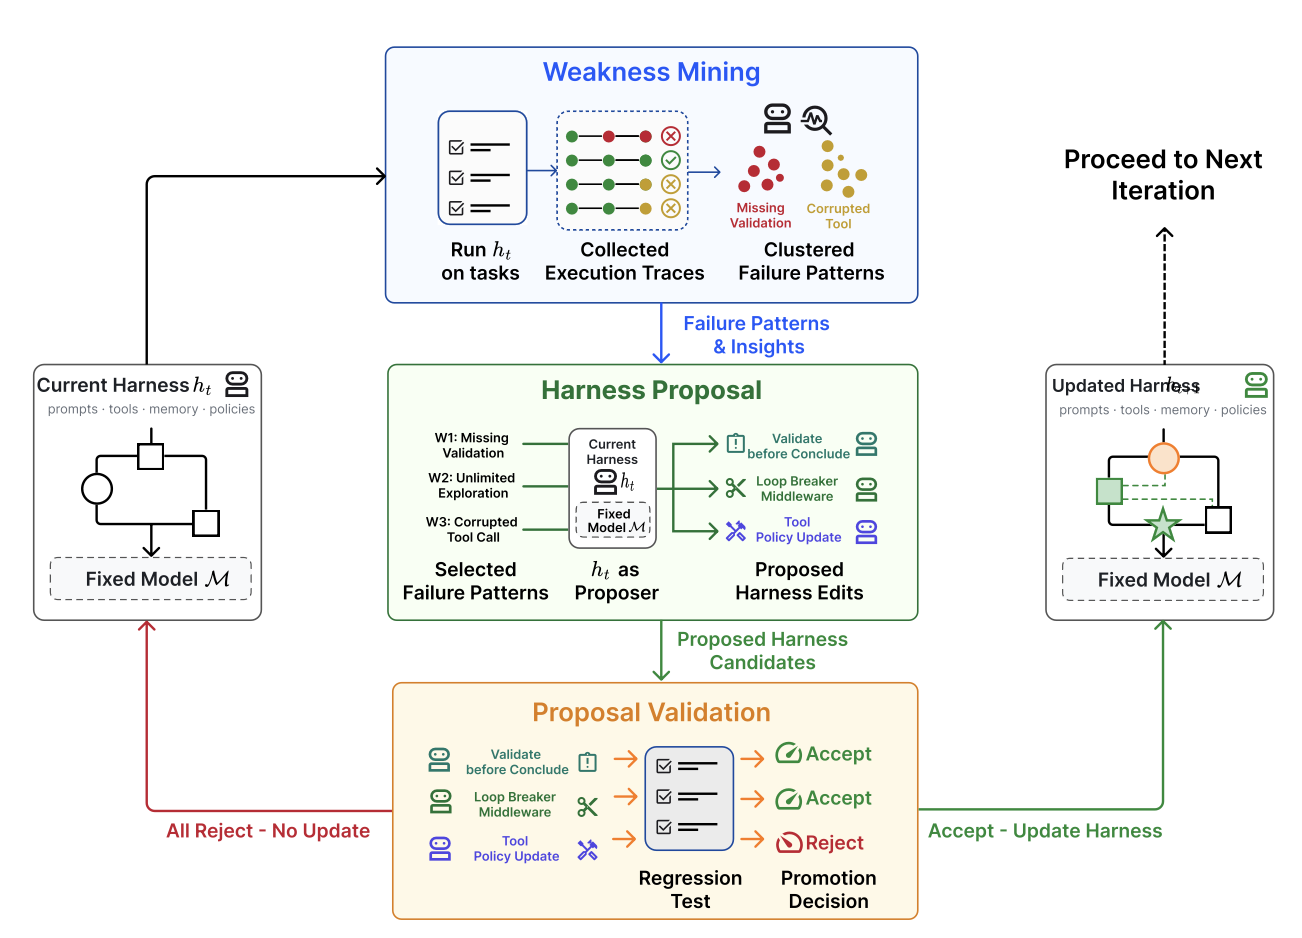
Self-Harness uses a loop of weakness mining, bounded harness proposal, and validation to update a harness. (Image source: Zhang et al. 2026 )
The loop in Self-Harness has three stages:
- Weakness mining: cluster failures into verifier-grounded failure patterns.
- The current harness
h_{t}is used to evaluate on tasks and execution traces are collected for analysis.- Note that two runs can share the same verifier outcome in the error logs on the surface, such as timeout or missing artifact, while having different causal mechanisms. Therefore we need a failure record of rich information, containing the terminal verifier-level cause, the causal status of the relevant agent behavior, and the abstract agent mechanism exposed by the trace, to uncover the root causes.
- The current harness
- Harness proposal: propose bounded harness edits based on mined failure patterns.
- The same model is invoked under
h_{t}as a proposer.- The model is provided with a bounded proposal context: (1) the editable surfaces of the current harness, (2) the verifier-grounded failure patterns from the evaluation system, (3) records of passing behaviors that should be preserved, and (4) summaries of previously attempted edits.
- Harness edits should prefer recurrent error patterns that are addressable (e.g. not task-specific difficulty) and can be resolved by narrow changes.
- Harness edit candidates should be distinct and diverse.
- The same model is invoked under
- Proposal validation: validate and merge qualified edits to create a new harness
h_{t + 1}.- Candidate edits are evaluated by regression tests on held-in
D_{\text{in}}(for testing whether the weakness is resolved) and held-outD_{\text{out}}(for checking whether other unknown issues were introduced) splits.- Candidates are accepted only if they have no regression on both held-in and held-out data.
- Accepted candidates are merged to update the harness to
h_{t + 1}, while rejected candidates are logged without changing the active harness.
- Candidate edits are evaluated by regression tests on held-in
When running MiniMax M2.5, Qwen3.5-35B-A3B, and GLM-5 on Terminal-Bench-2, Self-Harness was shown to learn model-specific harness instructions that target at different weaknesses of different base models and improve held-out pass rates.
Self-harness type of work does raise my concerns that if a program is allowed to edit the OS system, abstraction boundaries are broken. The editable surface needs to be properly designed and the permission control and security layers need to live outside this loop. All the challenges around reward hacking still remain.
Evolutionary Search
Evolutionary search is an optimization method inspired by natural selection (see my old post on evolutionary algorithm). It evolves a population of solutions by mutating them and only keeping those with high “fitness” in the crowd. Evolutionary search comes in handy when (1) the search space is extensive or weirdly shaped; and (2) it is hard to optimize directly with gradients but easy to evaluate solutions. Harness search seems to be a good fit here.
Evolutionary search has been used in prompt engineering in the past studies. Promptbreeder (Fernando et al. 2023) optimizes task-specific prompts through a rich set of mutation operations, and interestingly the mutation prompts (i.e. instructions to an LLM to mutate a task prompt) are themselves also improved through evolution. GEPA (Agrawal et al. 2025) combines reflection -based prompting with evolutionary search and uses natural language reflection over trajectories of trial and error to propose prompt updates.
Novikov et al. (2025) introduced AlphaEvolve as a coding-agent evolutionary search system, which stores a pool of candidate programs and prompts frozen LLMs to generate diffs for improvement. As the system repeatedly evaluates child programs and keeps successful ones, it discovers better solutions in time.
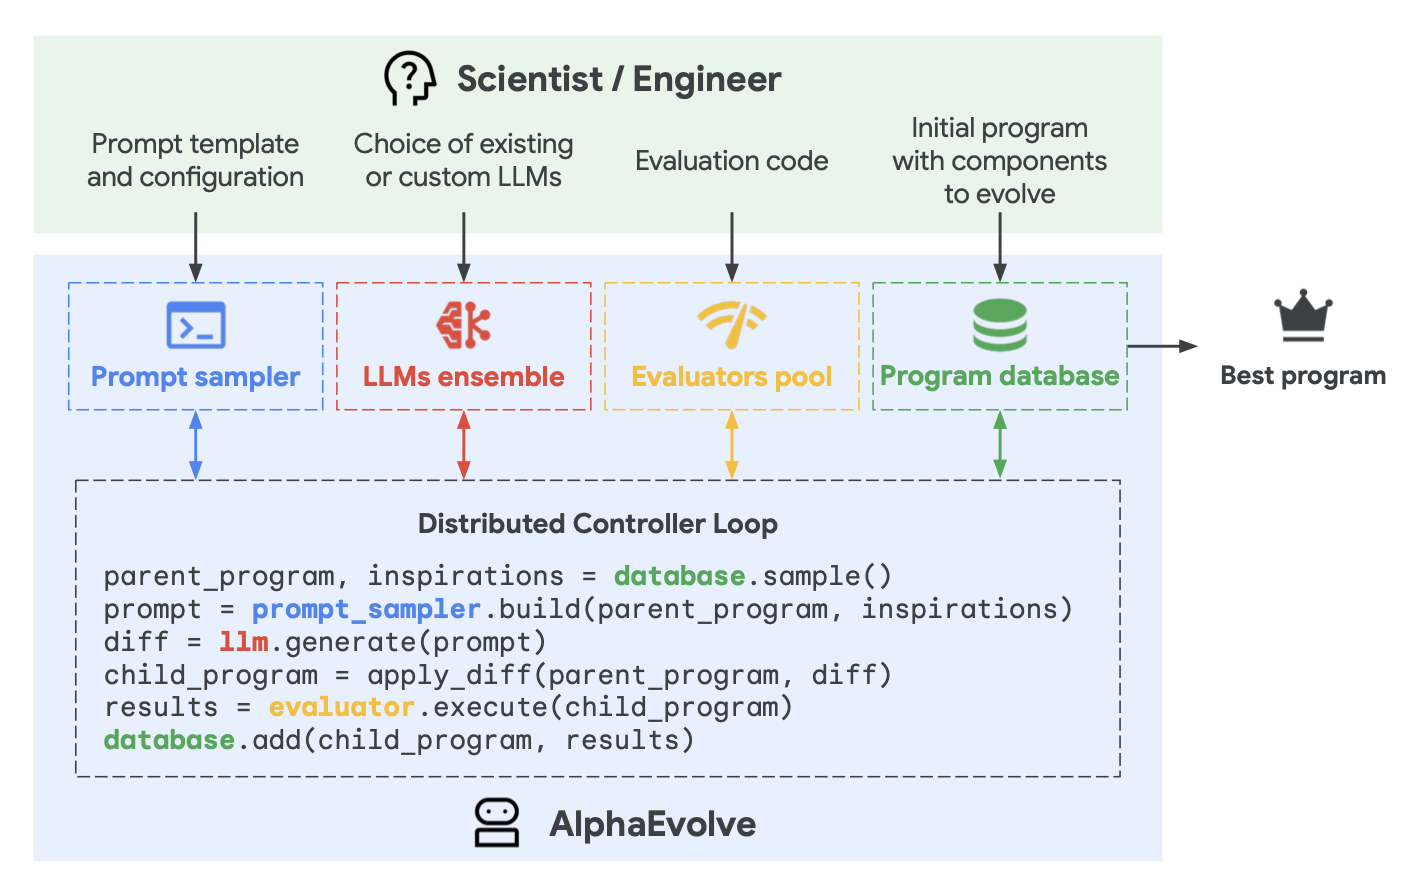
How AlphaEvolve works. (Image source: Novikov et al. 2025 )
A few details matter in the design of AlphaEvolve:
- The prompt includes parent programs, results, instructions, and sometimes meta information.
- The coding agent has access to the full repo, but code regions for improvement are explicitly marked with
# EVOLVE-BLOCK-STARTand# EVOLVE-BLOCK-END. - Meta-prompt co-evolves with instructions and context as suggested by LLM, in a similar way as how we evolve solution programs.
Ablations show the evolution procedure, context in prompts, meta-prompts, full-file evolution and the use of stronger LLMs.
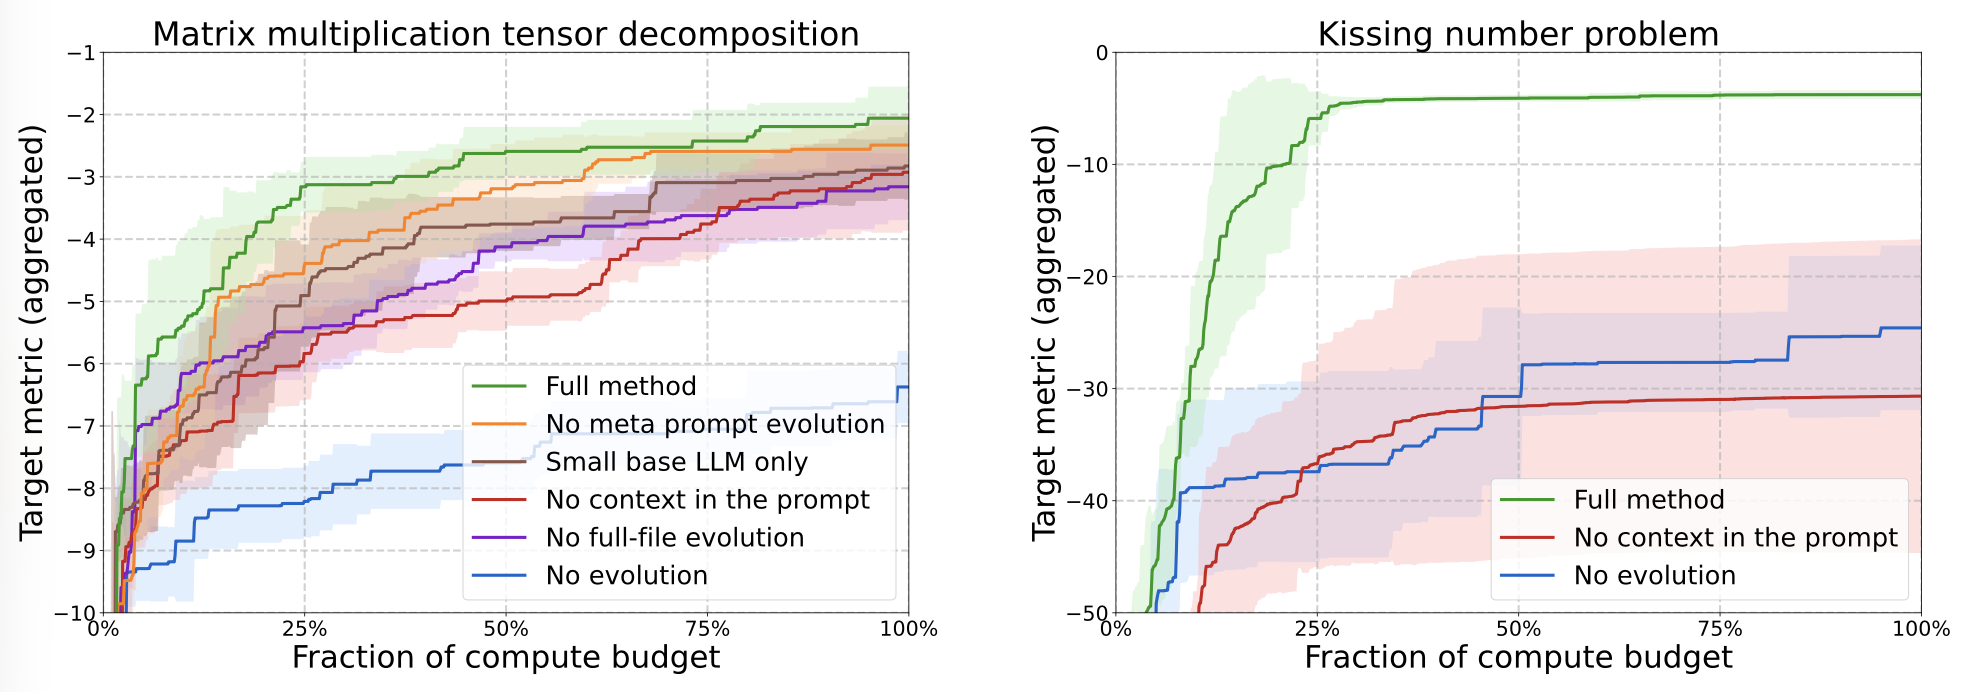
Ablations show the value of everal designs in AlphaEvolve. (Image source: Novikov et al. 2025 )
Recent variants such as ThetaEvolve (Wang et al. 2025) combines evolutionary search with RL and in-context learning. ShinkaEvolve (Lange et al. 2025), on the other hand, introduced three new components to improve LLM sampling efficiency:
- More sample-efficient exploration by designing parent sampling to balance performance rank and offspring count.
- Code-novelty rejection sampling by discarding candidates that are too similar to the existing population based on embedding-based cosine similarity.
- Identifying good patterns in successful solutions in a meta-scratchpad to guide future mutation.
Unlike the methods above, which focus on solution improvement, Darwin Gödel Machine (DGM; Zhang et al. 2025) explicitly targets the evolution of an editable harness-code repository with an LLM-based coding agent. Precisely, this agent is allowed to modify its own harness. A follow-up work on Hyperagents (Zhang et al. 2026) introduced a meta-agent to control how to modify existing task agents to create new ones.
- Start with one coding agent in the pool.
- In each iteration, pick one parent with a probability proportional to its performance and inversely to the number of children it has, to modify and branch off to produce new agents.
- The selected parent agent examines its own benchmark evaluation log and then proposes improvements to its own harness codebase to generate a new version of the coding agent. Code editing is implemented with two basic tools: (1) bash (args:
<bash_command>) and (2) editor (args:view/create/edit <file_path>). - New coding agents are evaluated, and only those with sufficiently high performance are added back into the pool.
- Repeat steps 2-4 until some stop criteria hit.
DGM is harness evolution under a fixed model. In experiments with Claude 3.5 Sonnet as the base LLM and simple initial harness configs, the DGM-discovered agents are comparable to or outperform handcrafted agents on SWE-bench Verified (20% to 50%) and Polyglot (14.2% to 30.7%).
This family of methods works well when candidate solutions are automatically evaluable and candidate fitness is easy to quantify, such as matrix multiplication, GPU kernel optimization, algorithm contests, datacenter scheduling. It struggles with domains where evaluation is slow, ambiguous, or mostly heuristic-based. The compute efficiency and effectiveness of evolution are also concerns.
Joint Optimization with Model Weights
Harness evolution changes the non-parametric system around the model. To enable full self-improvement, the model can totally be allowed to update its own weights at the same time. The weight update can be implemented via improvements in the model training pipeline or continual learning at test time. The topic of continual learning is worthy of its own post in the future.
SIA (Hebbar et al. 2026) is an early attempt to combine harness improvement and model-parameter updates in the same optimization loop, with three components in the design:
- Meta-Agent: proposes the initial harness.
- Task-Specific Agent: executes the task.
- Feedback-Agent: chooses whether to update the harness or the model weights based on recent trajectories.
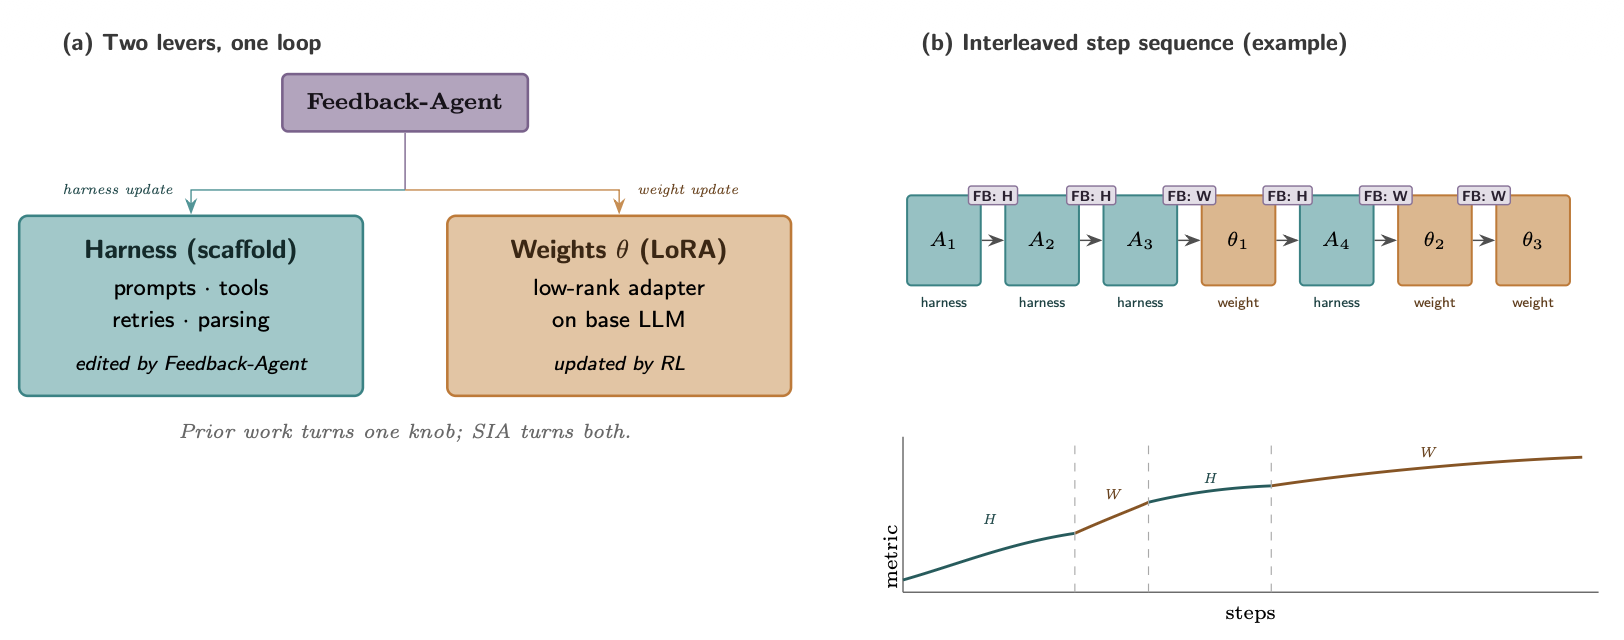
The Feedback-Agent in SIA decides the next iteration type. (Image source: Hebbar et al. 2026 )
There are a few confounding choices in SIA’s experiments that make the results hard to interpret. For example, the task-specific agent is much weaker than the models used for the Meta-Agent and Feedback-Agent (gpt-oss-120b vs Claude Sonnet 4.6), and the baselines are too weak to cross-reference cleanly against related methods. I would consider the direction interesting, but the evidence provisional. Yet many challenges, such as training stability and Goodhart effect, still remain open.
Future Challenges
The AI Scientist line of work is a strong demonstration that an expert-designed harness can coordinate a large portion of auto-research loop, experimented in the form of writing research papers. But paper production is not identical to scientific discovery. A system can write a plausible manuscript while still having fabricated citations, implementation drift, or weak experimental results.
Trehan & Chopra (2026) tested whether LLMs can go from a research idea to a paper with minimal scaffolding and basic tools (i.e., read_file, write_file, llm_search, list_files). Each idea had a dedicated workspace where agents could generate and read documents as part of context. They experimented in three domains (world models, multi-agent RL, AI safety & alignment), with each domain containing 45-50 high-quality seed documents to inspire new ideas. Only four ideas were selected by human experts to run through the full pipeline, and only one was fully executed into a paper. They observed six recurring failure modes in the experiments:
- Bias toward training-data defaults: use old libraries, stale commands, standard formats, or assumptions not grounded in the actual repository or dataset.
- Implementation drift under execution pressure: when implementation becomes technically complex, the model may move toward a common simpler solution rather than the proposed method.
- Memory and context degradation: long-horizon projects lose critical details unless logs are written as persistent artifacts.
- Over-optimism: the model declares success despite noisy or failed experiments, similarly observed as “p-hacking and eureka-ing” pattern by Bubeck et al. (2025) where models can introduce “numerical duct tape” and declare victory when signals are still noise.
- Insufficient domain intelligence: the model lacks tacit craft knowledge, e.g. predicting implementation complexity, judging whether an experimental result is plausible, or knowing which baselines matter.
- Weak scientific taste: experiments may be executable but fail to answer the right question.
Toward full RSI, researchers have made real progress, but several bottlenecks remain.
1. Weak and fuzzy evaluators. Many research claims do not have a fast and precise verifier, and the same is true for many real-world tasks. Current self-improvement loops work best for tasks when evaluation metrics are measurable and objective, similar as how RL works.
Research taste, novelty, and long-term scientific value are much harder to measure. For example, research taste often mixes problem framing, experimental design, and judgment about which surprising results are worth pursuing and which failure cases are worth retries.
2. Context and memory lifecycle. Memory grows as AI agents become more autonomous and independent. A useful harness needs to manage context and memory to complement existing limitation in long-context generation while still maximizing the success of long-horizon tasks. Since humans are able to maintain memory through our life time, I see an anoloy here that context engineering will and should become a core part of intelligence, rather than staying in the software system layer.
3. Negative results. Researchers are incentivized to publish successful results and thus literature is biased toward successes. LLMs trained on a vast amount of data (mostly human created, at least for now, lol) may be bad at deciding when to abandon a hypothesis, report a negative result, or even acknowledge a failure due to the imablance of success vs failure cases in data. A research harness should make failed attempts easy to preserve, as learning from failure is the best way to trim down the task search space.
4. Diversity collapse. Evolutionary and RL loops tend to exploit known high-reward patterns. We need mechanisms to prevent the population from collapsing into variants of the same solution. This is especially critical for open-ended research, where the best path may initially look worse under the current evaluator.
5. Reward hacking. A self-improvement loop optimizes whatever signal it is given. If the reward comes from unit tests, the agent may overfit to tests; if it comes from a judge model, it may learn reward hacking tricks specific to this judge; if it comes from benchmark scores, it may exploit benchmark artifacts.
The evaluator and permission control should likely sit outside the loop that evolves harness, with held-out tests, trace audits, and human review at decision points that matter—how much oversight can be scaled up and automated remains an open research area.
6. Long-term success. An extrinsic loop of optimization works on rewards outside of individual rollouts that we can simulate in training sandbox.
Take coding agent as an example. Coding agents have already increased daily productivity in software engineering, but many optimization goals are still too short-term. It can often complete the task at hand, but less obvious how it should protect the long-term health of a repo collectively maintained by hundreds or thousands of engineers. Standard sandbox-based RLVR-style training rarely captures maintainability, ownership boundaries, migration cost, backwards compatibility, or future debugging burden.
7. The role of humans. Humans should move up the stack, not be removed from the loop, meaning that human should provide oversight at the right time, at the right abstraction level and our system design should consider when and how to set up such touch points.
Many challenges listed above need human’s feedback and steering. After all, we are building the technology for better future of humanity, not other way around.
Citation
Please cite this work as:
Weng, Lilian. “Harness Engineering for Self-Improvement”. Lil’Log (Jul 2026). https://lilianweng.github.io/posts/2026-07-04-harness/
Or use the BibTeX citation:
@article{weng2026harness,
  title = {Harness Engineering for Self-Improvement},
   = {Weng, Lilian},
  journal = {lilianweng.github.io},
  year = {2026},
  month = {July},
  url = "https://lilianweng.github.io/posts/2026-07-04-harness/"
}
Appendix: Some useful benchmarks
- PaperBench: replicate 20 ICML 2024 Spotlight and Oral papers from scratch, including understanding paper contributions, developing a codebase, and successfully executing experiments.
- Each replication task is decomposed into smaller, individually gradable tasks.
- 8,316 rubrics in total, co-developed with the paper authors.
- The best model at the time (
Claude 3.5 Sonnet, ~21%) does not outperform ML PhDs. - Includes PaperBench, PaperBench Code-Dev (a lighter version), and JudgeEval.
- Each replication task is decomposed into smaller, individually gradable tasks.
- CORE-Bench: evaluate computational reproducibility of published research.
- 270 tasks based on 90 scientific papers across computer science, social science, and medicine.
- Tasks involve reproducing results from provided code and data.
- Includes multiple difficulty levels and both language-only and vision-language tasks.
- The best reported agent at the time (
GPT-4oandGPT-4o-mini) achieved only 21% accuracy on the hardest task.
- 270 tasks based on 90 scientific papers across computer science, social science, and medicine.
- ScienceAgentBench: evaluate LLM agents for data-driven scientific discovery.
- Extracts 102 tasks from 44 peer-reviewed publications in four disciplines (math, chemistry, biology, geography).
- Covers basic data-science tasks in these domains: data processing, model development, data analysis, and information visualization.
- Extracts 102 tasks from 44 peer-reviewed publications in four disciplines (math, chemistry, biology, geography).
- RE-Bench: evaluate frontier AI agents on realistic ML research-engineering envs against human experts.
- 7 challenging, open-ended ML research-engineering environments.
- Each environment = (scoring function, starting solution, reference solution); each can be run with 8 or fewer H100 GPUs.
- Examples: optimize a kernel, run a scaling-law experiment, fix an embedding, fine-tune GPT-2 for QA, etc.
- Includes data from 71 eight-hour attempts by 61 distinct human experts.
- Human experts achieved non-zero score in 82% of 8-hour attempts; 24% matched or exceeded strong reference solutions.
- Best AI agents scored 4× higher than humans at a 2-hour budget, but humans had better returns to longer budgets and exceeded agents at 8-hour and 32-hour settings.
- 7 challenging, open-ended ML research-engineering environments.
- MLE-bench: evaluate ML engineering agents on offline Kaggle competitions.
- Contains 75 ML-engineering competitions curated from Kaggle.
- Tests training models, preparing datasets, running experiments, and submitting predictions to grading scripts.
- Uses Kaggle public leaderboards as human baselines.
- Best setup in the paper,
o1-previewwith AIDE scaffolding, reached at least Kaggle bronze-medal level in 16.9% of competitions. - Includes resource-scaling and contamination analyses.
- Contains 75 ML-engineering competitions curated from Kaggle.
- KernelBench: evaluate correctness and speed for generated GPU kernels.
- 250 PyTorch tasks to evaluate whether LLM can write fast and correct kernels.
- The evaluation metric fast_p = the percentage of generated kernels that are correct and faster than baseline.
- 250 PyTorch tasks to evaluate whether LLM can write fast and correct kernels.
References
[1] Good, I. J. “Speculations Concerning the First Ultraintelligent Machine.” Advances in Computers, 6:31–88, 1965.
[2] Yudkowsky, Eliezer. “Recursive Self-Improvement.” LessWrong, 2008.
[3] Choi, et al. “Anchored Self-Play for Code Repair.” ICML 2026.
[4] Zhao, et al. “Absolute Zero: Reinforced Self-play Reasoning with Zero Data.” arXiv preprint arXiv:2505.03335, 2025.
[5] Yuan, et al. “Self-Rewarding Language Models.” arXiv preprint arXiv:2401.10020, 2024.
[6] Chen, et al. “Self-Play Fine-Tuning Converts Weak Language Models to Strong Language Models.” ICML 2024.
[7] Zhang, et al. “Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models.” ICLR 2026.
[8] Ye, et al. “Meta Context Engineering via Agentic Skill Evolution.” arXiv preprint arXiv:2601.21557, 2026.
[9] Lee, et al. “Meta-Harness: End-to-End Optimization of Model Harnesses.” arXiv preprint arXiv:2603.28052, 2026.
[10] Lu, et al. “Towards end-to-end automation of AI research.” Nature, 651:914–919, 2026.
[11] Meng, et al. “ScientistOne: Towards Human-Level Autonomous Research via Chain-of-Evidence.” arXiv preprint arXiv:2605.26340, 2026.
[12] Kulikov, et al. “Autodata: An agentic data scientist to create high quality synthetic data.” arXiv preprint arXiv:2606.25996, 2026.
[13] Hu, Lu, and Clune. “Automated Design of Agentic Systems.” ICLR 2025.
[14] Madaan, et al. “Self-Refine: Iterative Refinement with Self-Feedback.” NeurIPS 2023.
[15] Zhang, et al. “AFlow: Automating Agentic Workflow Generation.” ICLR 2025.
[16] Zelikman, et al. “Self-Taught Optimizer (STOP): Recursively Self-Improving Code Generation.” COLM 2024.
[17] Zhang, et al. “Self-Harness: Harnesses That Improve Themselves.” arXiv preprint arXiv:2606.09498, 2026.
[18] Fernando, et al. “Promptbreeder: Self-Referential Self-Improvement Via Prompt Evolution.” arXiv preprint arXiv:2309.16797, 2023.
[19] Agrawal, A. et al. “GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning.” arXiv preprint arXiv:2507.19457, 2025.
[20] Novikov, et al. “AlphaEvolve: A coding agent for scientific and algorithmic discovery.” arXiv preprint arXiv:2506.13131, 2025.
[21] Lange, Imajuku, and Cetin. “ShinkaEvolve: Towards Open-Ended And Sample-Efficient Program Evolution.” arXiv preprint arXiv:2509.19349, 2025.
[22] Wang, et al. “ThetaEvolve: Test-time Learning on Open Problems.” arXiv preprint arXiv:2511.23473, 2025.
[23] Zhang, et al. “Darwin Gödel Machine: Open-Ended Evolution of Self-Improving Agents.” arXiv preprint arXiv:2505.22954, 2025.
[24] Zhang, et al. “Hyperagents.” arXiv preprint arXiv:2603.19461, 2026.
[25] Yuksekgonul, et al. “Learning to Discover at Test Time.” arXiv preprint arXiv:2601.16175, 2026.
[26] Riaz, et al. “Epistemic Uncertainty for Test-Time Discovery.” arXiv preprint arXiv:2605.11328, 2026.
[27] Hebbar, et al. “SIA: Self Improving AI with Harness & Weight Updates.” arXiv preprint arXiv:2605.27276, 2026.
[28] Trehan and Chopra. “Why LLMs Aren’t Scientists Yet: Lessons from Four Autonomous Research Attempts.” arXiv preprint arXiv:2601.03315, 2026.
[29] Bubeck 等人。 “使用 GPT-5 进行早期科学加速实验。” arXiv 预印本 arXiv:2511.16072,2025 年。
[30] Starace 等人。 “PaperBench:评估人工智能复制人工智能研究的能力。” ICML 2025。
[31] Wijk 等人。 “RE-Bench:评估语言模型代理相对于人类专家的前沿 AI 研发能力。” ICML 2025。
[32] Chan 等人。 “MLE-bench:在机器学习工程上评估机器学习代理。” arXiv 预印本 arXiv:2410.07095,2024 年。
[33] Chen 等人。 “ScienceAgentBench:面向数据驱动科学发现的语言代理的严格评估。” ICLR 2025。
[34] Siegel 等人。 “CORE-Bench:通过计算可重复性代理基准测试来提高已发表研究的可信度。” TMLR 2024。
[35] Ouyang 等人。 “KernelBench:LLM 能否编写高效的 GPU 内核?” arXiv 预印本 arXiv:2502.10517,2025 年。